One API for every AI model your product uses.
AetherGrid sits between your application and the AI providers. Send one request and it picks the right model, handles failures, and shows you exactly what each call cost.
01application· project API keys · one per integration
- support-agentlive
- search-reranklive
- triagelive
- eval-runnertest
- docs-qalive
- summariserlive
- playgroundtest
02aethergrid router
req_01jcn214z0emt2djsvvv4n- received
- ranked
- dispatched
- recorded
- strategy
- cost · policy: require_tools · min_context_window 128,000
- candidates
- 8 → 7 eligible · gemini-2.5-flash: circuit breaker open
- chosen
- claude-haiku-4.5 via experiential-labs
- routing_reason
- cheapest eligible candidate at $1.20/M input
03models · providers· from the registry · your price per 1M input · illustrative
llama-3.3-70b-instruct
self-hosted
330 ms$0.14/M
fast
mistral-large-3
self-hosted
290 ms$0.24/M
balanced
deepseek-v3.2
self-hosted
640 ms$0.34/M
balanced
claude-haiku-4.5
experiential-labs
460 ms$1.20/M
succeeded
claude-sonnet-4.5
anthropic
940 ms$3.60/M
balanced
claude-opus-4.6
anthropic
1420 ms$18.00/M
frontier
gpt-5.1
openai
1180 ms$1.50/M
frontier
gemini-2.5-flash
google
—
circuit breaker open
04observability / requests· every call, retrievable by id
| time | key | model | provider | strategy | status | latency | tokens | your cost |
|---|---|---|---|---|---|---|---|---|
| ··:··:··.··· | docs-qalive | claude-haiku-4.5 | experiential-labs | cost | succeededfallback | 488 ms | $0.008064 | |
| ··:··:··.··· | eval-runnertest | claude-sonnet-4.5 | anthropic | explicit | succeeded | 962 ms | $0.010044 | |
| ··:··:··.··· | support-agentlive | llama-3.3-70b-instruct | self-hosted | cost | succeeded | 341 ms | $0.000364 | |
| ··:··:··.··· | triagelive | gpt-5.1 | openai | quality | succeededstream | 1,204 ms | $0.010734 | |
| ··:··:··.··· | search-reranklive | mistral-large-3 | self-hosted | latency | succeeded | 276 ms | $0.000253 |
- Providers
- Six providers, one integration
- anthropic · openai · google · azure-openai · experiential-labs · self-hosted
- Routing
- Pick by cost, speed, quality or balance
- explicit · cost · latency · quality · balanced
- Cost
- The price of every call, on every response
- cost_usd · cost_is_estimated · routing_reason
request / lifecycle
Watch a request move
through AetherGrid.
Press run and follow one request from arrival to record. You will see the rules it is checked against, the models considered, the one that wins and why, the response, and the entry it leaves in your request log.
POST /v1/chat/completions with your key."Summarize this document and identify the key risks."
projectproduction
strategyquality
strategyquality · quality tier, then cost
require_toolstrue
min_context_window128,000
candidates6
eligible4
eliminatedgemini-2.5-pro: circuit breaker open · gpt-5-mini: adapter unconfigured
rankingquality + cost
- claude-opus-4.6anthropic1420 ms$18.00/M
- gpt-5.1openai1180 ms$1.50/M
- claude-sonnet-4.5anthropic940 ms$3.60/M
- gemini-2.5-procircuit breaker open—ineligible
- gpt-5-miniadapter unconfigured—ineligible
- deepseek-v3.2self-hosted640 ms$0.34/M
— awaiting the router
— awaiting the router
— the request lands here, retrievable by id
Every AI request your product makes passes through one place that knows which model answered, why, and what it cost.
POST /v1/chat/completions·six adapters·four strategies·one request log
routing / strategies
The same request.
You choose what matters.
Pick cost, speed, quality or a balance. AetherGrid first removes any model it cannot actually call, such as a provider you have not connected or one that is currently failing, then ranks the rest and tells you, in plain words, which model won and why.
POST /v1/chat/route-preview.| model | adapter | p50 | your $/M in | tier | state |
|---|---|---|---|---|---|
| claude-opus-4.6 | anthropic | 1420 ms | 18.00 | 4 · frontier | same tier, 1420 ms at $18.00/M |
| gpt-5.1 | openai | 1180 ms | 1.50 | 4 · frontier | chosen |
| claude-sonnet-4.5 | anthropic | 940 ms | 3.60 | 3 · balanced | eligible |
| gemini-2.5-pro | 1260 ms | 1.50 | 3 · balanced | circuit breaker open | |
| deepseek-v3.2 | self-hosted | 640 ms | 0.34 | 3 · balanced | eligible |
| mistral-large-3 | self-hosted | 290 ms | 0.24 | 3 · balanced | eligible |
| claude-haiku-4.5 | experiential-labs | 460 ms | 1.20 | 2 · fast | eligible |
| gemini-2.5-flash | 520 ms | 0.36 | 2 · fast | circuit breaker open | |
| gpt-5-mini | azure-openai | 610 ms | 0.30 | 2 · fast | adapter unconfigured — no credential |
| llama-3.3-70b-instruct | self-hosted | 330 ms | 0.14 | 2 · fast | eligible |
rules from the project's routing policy: require_tools · min_context_window 128,000 · prices and response times are illustrative
{
  "primary": {
    "slug": "gpt-5.1",
    "provider": "openai"
  },
  "fallbacks": [
    { "slug": "claude-opus-4.6", "provider": "anthropic" }
  ],
  "strategy": "balanced",
  "reason": "highest tier (frontier); then speed and cost together, 1180 ms at $1.50/M",
  "considered": 7,
  "eliminated": [
    { "slug": "gemini-2.5-pro", "reason": "circuit breaker open" },
    { "slug": "gemini-2.5-flash", "reason": "circuit breaker open" },
    { "slug": "gpt-5-mini", "reason": "adapter unconfigured — no credential" }
  ]
}| adapter | configured | circuit_state | failures | success | probe |
|---|---|---|---|---|---|
| anthropic | true | closed | 0 | 99.8% | 412 ms |
| openai | true | closed | 0 | 99.6% | 388 ms |
| true | open | 5 | 41.0% | — | |
| experiential-labs | true | closed | 0 | 99.9% | 296 ms |
| self-hosted | true | closed | 0 | 100.0% | 61 ms |
| azure-openai | false · no credential | closed | 0 | — | — |
A provider that fails several times in a row is marked open and skipped; after a cooldown it is tried again, and a success marks it closed. Only genuine provider failures count, so a request that was itself malformed changes nothing. Skipping an open provider is what stops someone else's outage from becoming your slow day.
observability / usage
See every request.
Know every dollar.
Every call is recorded with its model, provider, response time, tokens and cost. Usage and spend are built from that same record, so the totals always add up to the requests you can see.
cost_is_estimated tells you which. An unknown cost is shown as unknown, never as zero.Requests
140,400
6 models · 4 adapters
p50 latency
405 ms
weighted by requests, from the log
Tokens in / out
324.4M / 24.7M
cached input not shown
Spend
$294.82
20% of a $1,500 advisory budget
| model | requests | spend | share |
|---|---|---|---|
| claude-haiku-4.5 | $143.52 | 49% | |
| gpt-5.1 | $72.00 | 24% | |
| claude-sonnet-4.5 | $32.04 | 11% | |
| llama-3.3-70b-instruct | $21.08 | 7% | |
| deepseek-v3.2 | $14.75 | 5% | |
| mistral-large-3 | $11.42 | 4% |
Spend is what you pay: the provider's reported cost plus the service markup. Every figure says whether the provider reported it or it was estimated. The cheapest model here carries 44% of requests for 7% of spend, which is exactly what routing by cost is for.
- mistral-large-3290
- llama-3.3-70b-instruct330
- claude-haiku-4.5460
- gemini-2.5-flash520
- gpt-5-mini610
- deepseek-v3.2640
- claude-sonnet-4.5940
- gpt-5.11,180
- gemini-2.5-pro1,260
- claude-opus-4.61,420
your own servers. Speed is measured from this workspace's own requests, not from a vendor's status page.
agents · workflows · evaluations
Build more than
a chat completion.
Assistants that use tools, workflows that chain steps together, and evaluations that score models against your own examples all run through the same gateway. Every step is logged and priced like a normal request, with an id you can open.
- 012 ms
triggertrigger
POST /v1/workflows/{id}/runs
- 02184 ms
fetchhttp_request
GET status-page incidents · 200
- 0396 ms
contextknowledge
runbooks · 4 chunks · pgvector hnsw
- 041,204 ms
draftmodelgpt-5.1
strategy: quality
req_01j3l9jp6c… · 3,860 / 412 tokens · $0.008945
- 051 ms
severitycondition
output.severity in [sev1, sev2] → true
- 063 ms
shapetransform
jsonpath · pick title, summary, owners
- 07221 ms
notifyhttp_request
POST on-call webhook · 202
- 081 ms
outputoutput
output_payload
- status
- succeeded
- latency_ms
- 1,712
- total_tokens
- 4,272
- total_cost_usd
- $0.008945
- 01succeeded88 ms
search_kbknowledge_search
help-centre · top 3 · score ≥ 0.72
- 02succeeded142 ms
lookup_orderhttp_request
GET /orders/{id} · 200
- 03succeeded4 ms
redactcode_transform
strip card digits before the model sees them
- 04succeeded318 ms
compose_replymodel_callllama-3.3-70b-instruct
cheapest eligible candidate
req_01j1u9f28g… · 2,140 / 186 tokens · $0.000313
- status
- succeeded
- latency_ms
- 552
- total_tokens
- 2,326
- total_cost_usd
- $0.000313
| case | scorer | score | vs base |
|---|---|---|---|
| refund-window | contains | 1.00 | same |
| partial-refund-math | exact_match | 1.00 | ▲ improved |
| policy-json | json_equals | 1.00 | same |
| order-id-format | regex | 1.00 | same |
| tone-apology | llm_judge | 0.62 | ▼ regressed |
| escalation-path | contains | 1.00 | same |
- passed_cases
- 5 / 6
- average_score
- 0.94
- regressions
- tone-apology
- total_cost_usd
- $0.0069
1 improvement, 1 regression against the baseline run on the same version of the test set. Only runs on the same version are compared, so editing your examples can never look like a regression.
One key, one request format, every model you might want to use.
Authorization: Bearer ag_live_…·live · test·GET /openapi.json
developers / api
Built for
developers.
A clean REST API, a published OpenAPI reference, and keys for live and test environments so staging can never spend your production budget. Point your code at one endpoint and change models without touching it again.
GET /openapi.json is generated from the running service, so it always matches what is deployed. Authenticate with Authorization: Bearer ag_… or an X-API-Key header.curl https://app.aethergridlabs.com/v1/chat/completions \
-H "Authorization: Bearer $AETHERGRID_API_KEY" \
-H "Content-Type: application/json" \
-d '{
"messages": [{"role": "user", "content": "Summarise this incident."}],
"strategy": "cost",
"max_tokens": 512
}'{
"request_id": "req_01j9r2m8k4x7v3p6q1w5e8t2y0",
"content": "Two services lost quorum at 09:41 after…",
"finish_reason": "stop",
"model": "llama-3.3-70b-instruct",
"provider": "self-hosted",
"routing_strategy": "cost",
"routing_reason": "cheapest eligible candidate at $0.12/M input",
"did_fallback": false,
"attempt_count": 1,
"usage": {
"input_tokens": 1840,
"output_tokens": 212,
"is_estimated": false
},
"latency_ms": 318.4,
"cost_usd": 0.000284,
"cost_is_estimated": true,
"customer_cost_usd": 0.000341
}cost_usd is the provider's price; customer_cost_usd is what you pay, with the service markup added. An unknown cost is null, never zero.| name | key | scopes | last_used | state |
|---|---|---|---|---|
| support-agent | ag_live_••••••••3f9c | inference:runrequests:read | 2s ago | active |
| search-rerank | ag_live_••••••••a71e | inference:run | 4s ago | active |
| triage | ag_live_••••••••c204 | inference:runrouting:read | 9s ago | active |
| eval-runner | ag_test_••••••••8d1b | inference:runevaluations:write | 1m ago | active |
| ci-smoke | ag_test_••••••••5e77 | inference:run | revoked 3d ago | revoked |
Every action is checked twice: against the key's permissions and against the role of the person who owns it (viewer, member, admin or owner). Both must allow it. A lost key is revoked and reissued; it cannot be recovered, because it was never stored.
- adapters
- anthropic
- openai
- azure-openai
- experiential-labs
- self-hosted
architecture
A small system
you can understand.
A web console, an API and a database. Your provider keys live only on the API server, never in the browser, and every request to a provider goes through the one gateway that records it.
- browser → console
- You sign in to the console. It talks to the API for you and never holds a provider key.
- console → api
- One hop over a private network. The API is where routing, logging and cost tracking happen.
- api → providers
- Provider credentials stay on the server. They are never returned by any endpoint and never reach the browser.
team
The people behind AetherGrid AI
AetherGrid AI is led by its founder and its CTO.
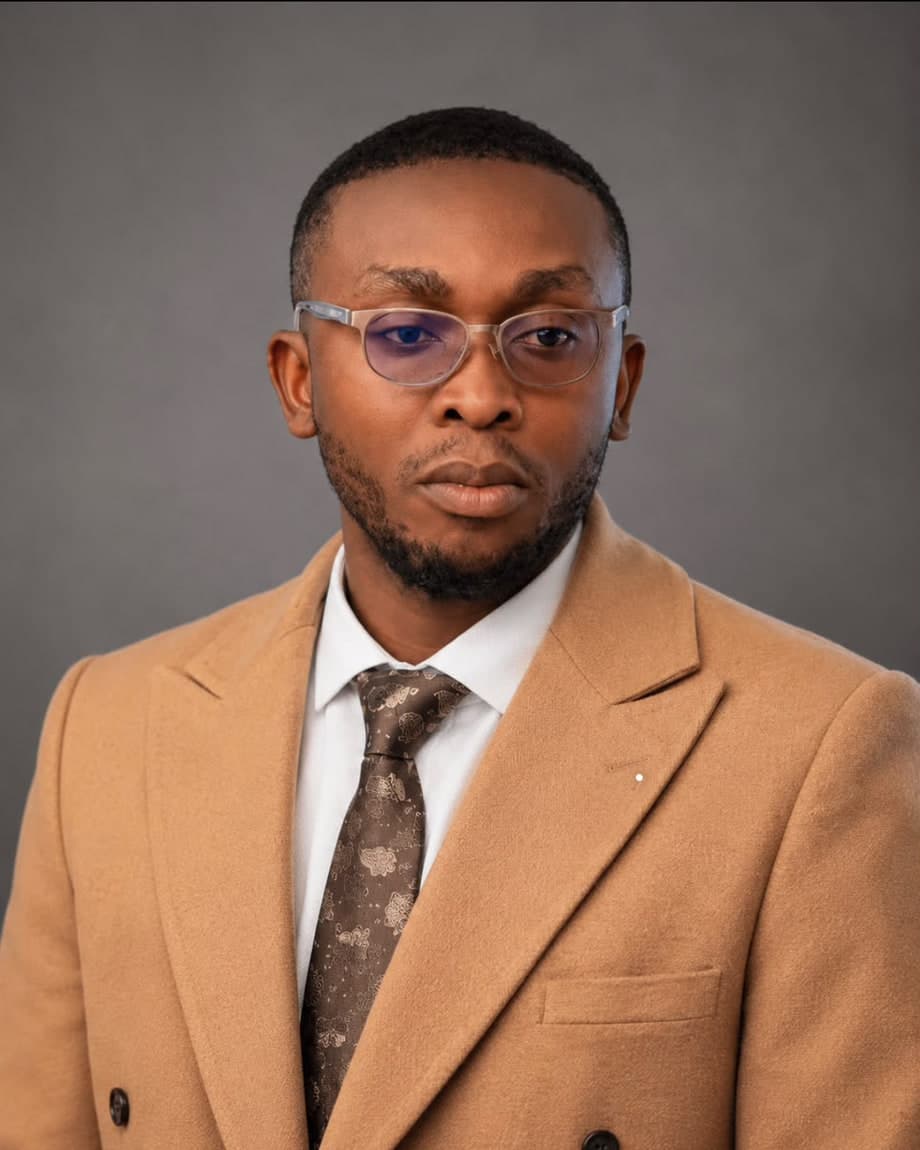
Chinazaekpere Ofodile
Founder, AetherGrid AI
LinkedInprofile for Chinazaekpere Ofodile, opens in a new tab
contact
Start with one request.
Keep every model open to you.
Create a free account and make your first request in minutes. If your team needs agreed limits or a private setup, tell us what you are building and we will set it up with you.